Architecture Overview
SMG is a high-performance inference gateway that sits between your applications and LLM workers. It provides unified routing, enterprise features, and full observability across heterogeneous model deployments.
System Architecture
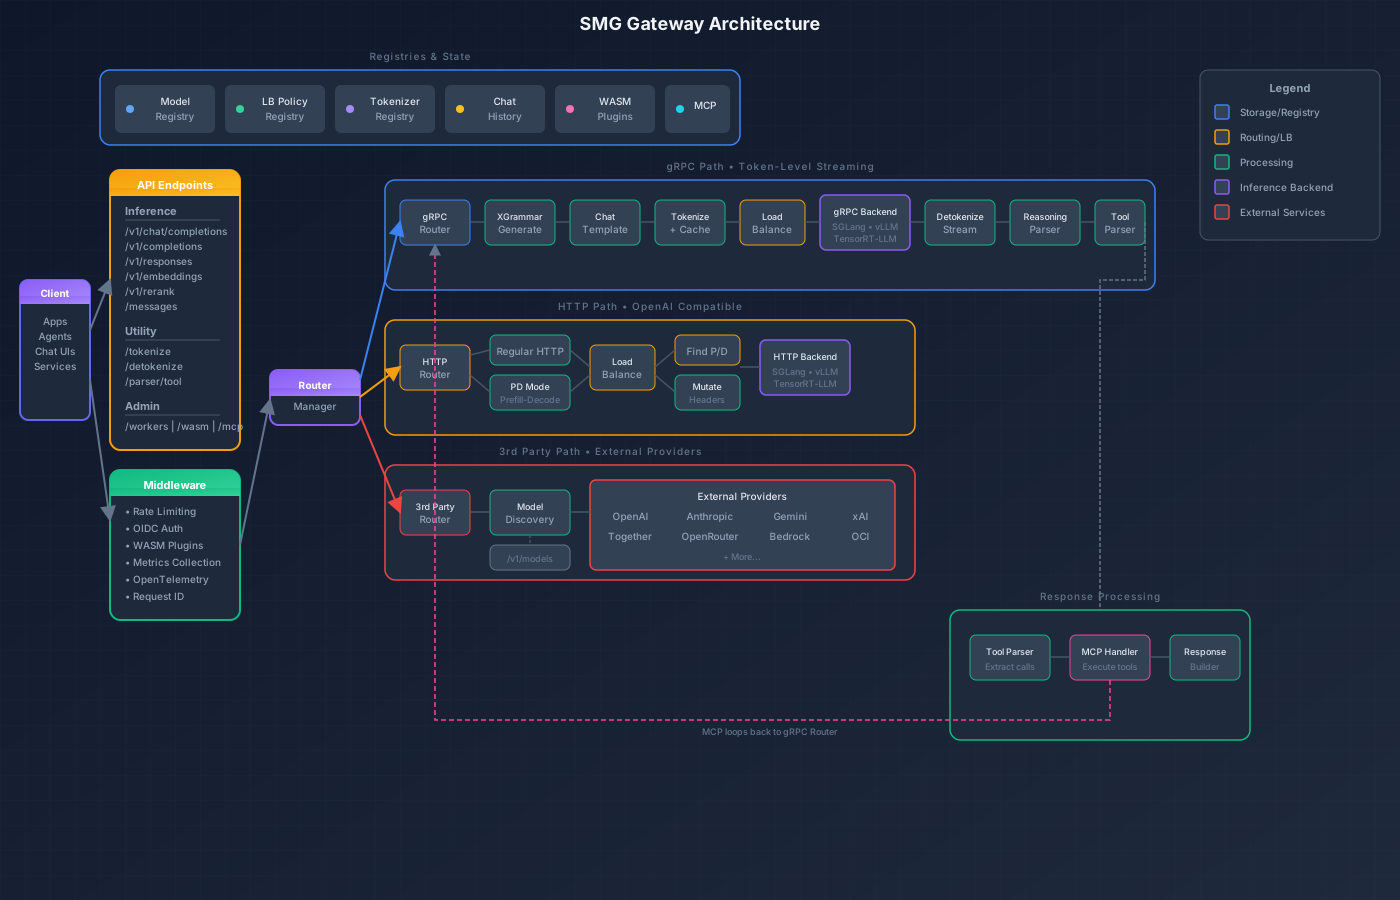
SMG reaches local inference engines over three worker paths, chosen per worker by the URL scheme. External provider APIs use the third-party path.
| Path | Worker URL | Engine side | Gateway role |
|---|---|---|---|
| gRPC | grpc://host:port |
Engine with a gRPC servicer (SGLang, vLLM, TensorRT-LLM, TokenSpeed, MLX) | Full pipeline: chat templates, tokenization, token-aware routing, reasoning and tool parsing |
| ZMQ | ipc:///path |
Headless engine core on the same host (vLLM, TokenSpeed) | The same pipeline, plus the request handling the engine's frontend or gRPC servicer would otherwise do |
| HTTP | http://host:port or https://host:port |
Engine's OpenAI-compatible server | Proxy: routing, retries, and failover |
Registries & State
Registries hold the configuration and state needed for request processing.
| Registry | Purpose | Used By |
|---|---|---|
| Model Registry | Maps model names to backends and capabilities | Router Manager |
| LB Policy Registry | Load balancing configurations per model | Self-hosted HTTP, gRPC, and ZMQ workers (external providers and realtime sessions go to the least-loaded worker instead) |
| Tokenizer Registry | Tokenizers for gateway-side processing | gRPC and ZMQ paths, /v1/tokenize, /v1/detokenize |
| Chat History | Multi-turn conversation context | Responses and Conversations APIs |
| WASM Plugins | Custom request/response transformations | Middleware |
API Endpoints
SMG exposes three categories of endpoints:
Inference APIs
| Endpoint | Description |
|---|---|
POST /v1/chat/completions |
OpenAI-compatible chat completions |
POST /v1/completions |
Text completions |
POST /v1/responses |
Agentic workflows with tool execution |
POST /v1/embeddings |
Embedding generation |
POST /v1/rerank |
Reranking API |
POST /v1/messages |
Anthropic Messages API |
Utility APIs
| Endpoint | Description |
|---|---|
POST /v1/tokenize |
Tokenize text using model's tokenizer |
POST /v1/detokenize |
Convert token IDs back to text |
POST /parse/function_call |
Parse tool calls from text |
POST /parse/reasoning |
Parse reasoning chains |
The two /parse/* routes sit behind control-plane auth, like the admin APIs.
Admin APIs
| Endpoint | Description |
|---|---|
GET/POST /workers |
Worker management |
GET/POST /v1/tokenizers |
Tokenizer management |
GET/POST /wasm |
WASM plugin management |
There is no admin API for MCP servers: static servers come from the --mcp-config-path file at startup, and a request can name its own. See the Extension API reference for every route and its auth tier.
Gateway Layer
The gateway layer handles cross-cutting concerns before requests reach the router.
Middleware Pipeline
| Component | Function |
|---|---|
| Admission Control | Off by default. --max-concurrent-requests caps concurrent requests gateway-wide, with a bounded FIFO queue; the priority scheduler admits by priority class instead |
| Authentication | Bearer API keys (--api-key, --tenant-api-key) on inference routes; control-plane API keys or JWT/OIDC with the admin role on control-plane routes |
| Tenant Resolution | Identifies the tenant from its API key, a trusted header (--trust-tenant-header), or the client IP |
| WASM Plugins | Custom request transformation logic |
| Request ID | Assigns unique ID for tracing |
| Metrics | Records latency, throughput, error rates |
| OpenTelemetry | Distributed tracing spans |
Per-tenant token and request budgets (tenant rate limiting) are enforced later, inside the gRPC router, not in this middleware.
Router Layer
The router layer handles LLM-specific request processing. It selects one of four routing paths based on worker type. By default SMG builds a single router at startup, chosen by the worker URL scheme, the PD mode, and --backend, and sends every request to it. With --enable-igw, it builds a router for each path and picks one per request from the workers that serve the requested model.
Router Manager
| Worker Type | Path Selected | Gateway Behavior |
|---|---|---|
| gRPC workers | gRPC Path | Full server - tokenization, chat templates, tool parsing |
| ZMQ workers | ZMQ Path | The gRPC router's pipeline, over local ipc:// sockets |
| HTTP workers | HTTP Path | Smart proxy - load balancing, PD disaggregation |
| External APIs | 3rd Party Path | Unified router - provider abstraction |
gRPC Path (Token-Level Streaming)
The gRPC path handles all text processing at the gateway and exchanges token IDs with the engine through its gRPC servicer.
Pipeline Stages
| Stage | Function |
|---|---|
| Chat Template | Apply model-specific chat template (Jinja2) |
| Tokenization | Convert text to token IDs using model tokenizer |
| Token Cache | Cache tokenized prefixes for reuse |
| Load Balance | Select a worker with the configured routing policy (cache_aware by default) |
| Detokenize | Convert streaming tokens back to text |
| Reasoning Parser | Extract thinking/reasoning from output (DeepSeek-R1, etc.) |
| Tool Parser | Parse function/tool calls from output |
Supported Backends
- SGLang (gRPC)
- vLLM (gRPC)
- TensorRT-LLM (gRPC)
- TokenSpeed (gRPC)
- MLX (gRPC, Apple Silicon)
ZMQ Path
The ZMQ path runs the same pipeline stages as the gRPC path, but talks to a headless engine core on the same host over local ipc:// sockets, with no engine API server or gRPC servicer in between.
Connection
| Step | Function |
|---|---|
| Bind | SMG binds request and output sockets for the worker's ipc:// path, plus a loopback TCP handshake port derived from that path |
| Handshake | The engine dials in and reports its context length and data-parallel size |
| Promote | The worker becomes routable as soon as the handshake completes |
| Dispatch | Requests go out as token IDs; output batches return token IDs with the engine's scheduler load piggybacked |
Gateway-Side Request Handling
Work that the engine's frontend or gRPC servicer does on the gRPC path moves into the gateway:
- Resolve stop strings to stop token IDs, or match them on the decoded text
- Attach EOS token IDs to each vLLM request
- Fan out
n > 1into single-sample engine requests - Pick the least-loaded engine inside a grouped data-parallel worker
Supported Backends
- vLLM (headless EngineCore)
- TokenSpeed (headless scheduler)
ZMQ workers can't serve as prefill or decode workers and have no KV-event stream. See ZMQ Direct Workers for setup and limits.
HTTP Path (OpenAI-Compatible)
The HTTP path supports two modes for OpenAI-compatible backends.
Regular HTTP Mode
Standard load balancing across HTTP workers running full inference.
PD (Prefill-Decode) Mode
With --pd-disaggregation, SMG sends each request to a prefill worker and a decode worker chosen as a pair: each leg has its own routing policy (--prefill-policy, --decode-policy), and a prefill pairs only with decode workers that share its KV transfer protocol. For SGLang, SMG dispatches both legs at once and adds the same bootstrap_host, bootstrap_port, and bootstrap_room to each JSON body, so the engines can meet and transfer the KV cache. For vLLM, SMG first sends prefill a one-token request, then passes the kv_transfer_params it returns (or, for Mooncake, parameters that SMG mints) to the decode leg. The client receives the decode worker's response. The gRPC path offers the same disaggregation for SGLang, vLLM, and TokenSpeed, plus encode-prefill-decode (EPD); see PD Disaggregation.
Supported Backends
- SGLang (HTTP)
- vLLM (HTTP)
- Other OpenAI-compatible servers: SMG registers a server whose engine it cannot identify with the
genericruntime
Third-Party Path
The third-party path routes to external LLM providers through a unified interface.
Model Discovery
When an external worker is registered with an API key, the gateway reads the provider's /v1/models to learn which models to route there; without a key, the worker accepts any model. GET /v1/models leaves provider models out unless the caller sends its own provider key, in which case SMG asks the providers' /v1/models with that key. See Model Discovery.
Supported Providers
| Provider | API Style |
|---|---|
| OpenAI | OpenAI |
| Anthropic | Messages |
| Google Gemini | Gemini |
| xAI Grok | OpenAI |
| Together AI | OpenAI |
| OpenRouter | OpenAI |
| AWS Bedrock | OpenAI-compatible |
| OCI Generative AI | OpenAI-compatible |
Response Processing
Response processing differs by path. On the gRPC and ZMQ paths, SMG parses tool calls and reasoning out of the model output itself. On the HTTP path, the engine's own server does that and SMG passes the response through. The MCP loop runs only in the Responses API (on gRPC or ZMQ workers, or with an OpenAI-compatible provider) and in the Messages API with the Anthropic provider; see Where MCP Runs.
Components
| Component | Function |
|---|---|
| Tool Parser | Extracts function/tool calls from model output (gRPC and ZMQ paths) |
| MCP Handler | Executes tools via Model Context Protocol servers |
| Response Builder | Assembles final response with tool results |
MCP Loop
When the model requests tool execution:
- The model's output contains a tool call (on gRPC and ZMQ workers, SMG's tool parser extracts it)
- MCP handler executes the tool
- SMG appends the call and its result to the conversation and calls the model again
- Loop continues until the model answers without a tool call or a tool-loop limit stops it
Load Balancing
Self-hosted workers (HTTP, gRPC and ZMQ) are placed by the policy set with --policy (default cache_aware) through one shared policy registry, and PD mode can set a policy per leg. External providers and realtime sessions are placed on the least-loaded worker instead.
| Policy | Algorithm | Best For |
|---|---|---|
cache_aware |
Prefix-tree matching, then lowest expected wait | Production default |
least_load |
Lowest expected wait: queued token work over throughput, plus KV-cache pressure | Load-aware routing on gRPC workers |
power_of_two |
Sample two, pick the lower expected wait | Load balancing on large fleets |
bucket |
Request-length buckets with adaptive boundaries | PD prefill leg |
consistent_hashing |
Hash ring with virtual nodes | Session affinity |
prefix_hash |
Prefix hash on a consistent ring, with a load check | Lightweight cache locality |
manual |
Explicit routing key mapping | Stateful chat |
round_robin |
Sequential cycling per candidate set | Even distribution |
random |
Uniform random | Testing |
passthrough |
First available worker | Single-worker gateways |
Cache-Aware Routing
The default cache_aware policy balances KV cache reuse against load:
- Match the request's prefix (text or token IDs) against a per-model tree of the prefixes routed to each worker, or against the engines' own KV-cache events when gRPC workers publish them
- If a worker holds enough of the prefix (above
--cache-thresholdin tree mode), the workers holding it are the candidates; otherwise every available worker is - Skip a holder whose in-flight requests exceed the mean across available workers by more than
--balance-abs-thresholdand are also above--balance-rel-threshold× that mean; if every holder is skipped, the other available workers that pass the same check become the candidates - Route to the candidate with the lowest expected wait (the
least_loadscore), breaking exact ties at random
See Cache-Aware Routing for KV-event mode, the hash index, and KV-pressure tuning.
Resilience
Built-in resilience features protect against failures.
| Feature | Function |
|---|---|
| Circuit Breaker | Stops routing to a worker after consecutive failures, under every routing policy |
| Retry Handler | Retries failed requests with exponential backoff |
| Health Checker | Periodic worker health probes |
| Timeout Manager | Request and connection timeouts |
What's Next?
- Service Discovery - Automatic worker discovery in Kubernetes
- gRPC Pipeline - Token-level streaming implementation
- High Availability - Multi-instance mesh networking
- Load Balancing - Routing policy deep dive
- Cache-Aware Routing - KV cache optimization
- PD Disaggregation - Prefill-decode separation