Concepts
This section explains the core concepts behind Shepherd Model Gateway. Understanding these concepts helps you design, deploy, and operate SMG effectively.
What is SMG?
Shepherd Model Gateway is an inference gateway that adapts to your deployment:
| With gRPC Workers | With HTTP Workers | With External APIs |
|---|---|---|
| Full OpenAI server | Intelligent proxy | Unified routing |
| Tokenization + caching | Load balancing | Model discovery |
| Tool parsing + MCP | PD disaggregation | Provider abstraction |
| Reasoning loops | Health-aware failover | API translation |
Unlike generic load balancers, SMG understands LLM patterns: prefix caching, token streaming, and KV cache affinity.
Core Components
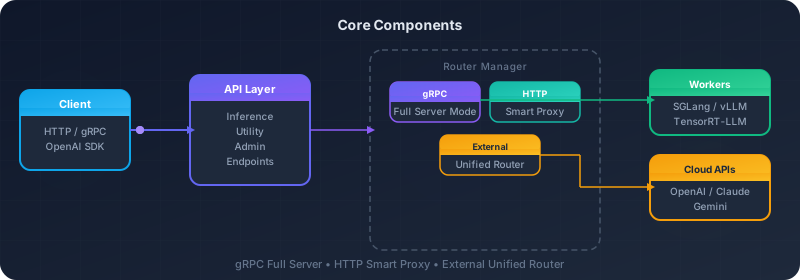
| Layer | Purpose |
|---|---|
| API Layer | Inference, utility, and admin endpoints |
| Router Manager | Selects path based on worker type |
| Service Discovery | Health monitoring, worker registration |
Key Concepts
Load Balancing
Routing strategies from simple random selection to cache-aware algorithms.
Performance
Tokenizer caching, request body streaming, and pooled upstream connections (optionally over HTTP/2) for high-throughput deployments.
Extensibility
WASM plugins and MCP integration for custom middleware and external tools.
Reliability
Circuit breakers, retries, health checks, rate limiting, overload protection, and graceful shutdown for resilient deployments.
Concept Categories
Architecture
Understand how SMG is structured internally:
- Architecture Overview — High-level system design
- Service Discovery — Kubernetes integration and worker registration
- gRPC Pipeline — Token-level streaming implementation
- Multimodal Pipeline — How images and video reach gRPC workers
- High Availability — Multi-instance mesh networking
Routing
Learn how SMG selects workers for requests:
- Load Balancing — Available routing policies
- Cache-Aware Routing — Prefix-based worker affinity
- Sticky Sessions and Routing Keys — Pin every request of a conversation to one worker
- PD Disaggregation — Separate prefill and decode workers
Performance
Optimize SMG for high-throughput deployments:
- Tokenizer Caching — Two-level cache for tokenization
- Request Streaming and Upstream Connections — Stream-or-buffer request bodies, upstream HTTP/2, and connection pooling
Extensibility
Extend SMG with custom logic and external tools:
- WASM Plugins — Dynamic middleware with WebAssembly
- Model Context Protocol — External tool integration via MCP
Reliability
Understand how SMG handles failures:
- Circuit Breakers — Preventing cascade failures
- Rate Limiting — Gateway concurrency limits and request queuing
- Tenant Rate Limiting — Per-tenant token and request budgets
- Priority Scheduling — Priority classes, reserved capacity, and preemption
- Overload Protection — Excluding saturated workers and shedding load
- Retries — Retrying transient failures with backoff
- Health Checks — Detecting unhealthy workers and taking them out of rotation
- Graceful Shutdown — Draining in-flight requests before the gateway stops
Design Principles
SMG is built on several core principles:
Transparency: SMG should be invisible to well-behaved applications. The same requests that work against a single worker should work through SMG.
Performance: Routing decisions happen in microseconds. SMG never becomes the bottleneck.
Reliability: Individual worker failures don't cause application failures. SMG routes around problems automatically.
Observability: You can always understand what SMG is doing through metrics, traces, and logs.
Simplicity: Common cases are simple. Advanced features are available but not required.